Insights
World Labs Atlas: what a world model means for AI and physics
World Labs announced Atlas on 1 September 2026 and I still cannot use it: no public API, no price, no paper, no frame rate, a request form and an unnamed partner list. I wrote it up as a buyer's guide first. That was the wrong lens. The interesting thing about Atlas is not what it costs, it is what it was trained on. For the first time at scale, a lab has treated 3D Gaussian splats as a native input alongside words, pixels and video. This post is about who is doing that, what a splat is, why people who think about AI's direction reacted the way they did, what the physics benchmarks say, and, at the end, what a studio my size can actually do with the parts that ship today.
Who is building this, and why she says words are not enough
Fei-Fei Li co-founded World Labs in 2024 and leads it; Diamandis introduced her as its CEO. Before that she is the person who, starting at Princeton in 2007, led ImageNet, the dataset of more than 14 million labelled images that made the 2012 deep-learning breakthrough measurable. She is a professor of computer science at Stanford and co-director of its Institute for Human-Centered AI, and her 2023 memoir is called The Worlds I See. In 2025 she received the Queen Elizabeth Prize for Engineering and was named among Time's "Architects of AI" (Wikipedia, read 5 September 2026).
Her argument for World Labs is in an essay she published on 10 November 2025, From Words to Worlds. On language models:
Yet they remain wordsmiths in the dark; eloquent but inexperienced, knowledgeable but ungrounded.
She has made the same argument since her 2024 TED talk, which opens on a black screen: "This was the world 540 million years ago. Pure, endless darkness. It wasn't dark due to a lack of light. It was dark because of a lack of sight." Sight came first, then everything sight made possible, and language last. In the essay the claim is that "Spatial Intelligence represents the frontier beyond language". She sets out three things a world model must be: generative, producing worlds "with perceptual, geometrical, and physical consistency"; "multimodal by design"; and interactive, able to "output the next states based on input actions". Read those three against the Atlas post and they line up almost word for word. The essay is the specification; Atlas is the first public attempt at it.
Peter Diamandis, discussing the launch on his Moonshots podcast on 5 September, put it more simply: "Dr. Fei-Fei Li, CEO of World Labs, who just released Atlas, the world's first multimodal world model that generates image and video frames with pixel perfect camera controls and reconstructs them in 3D" (Moonshots, from 1:15:07). He also said she would be on the show in a couple of weeks. I will be listening for a frame rate.
What is a Gaussian splat?
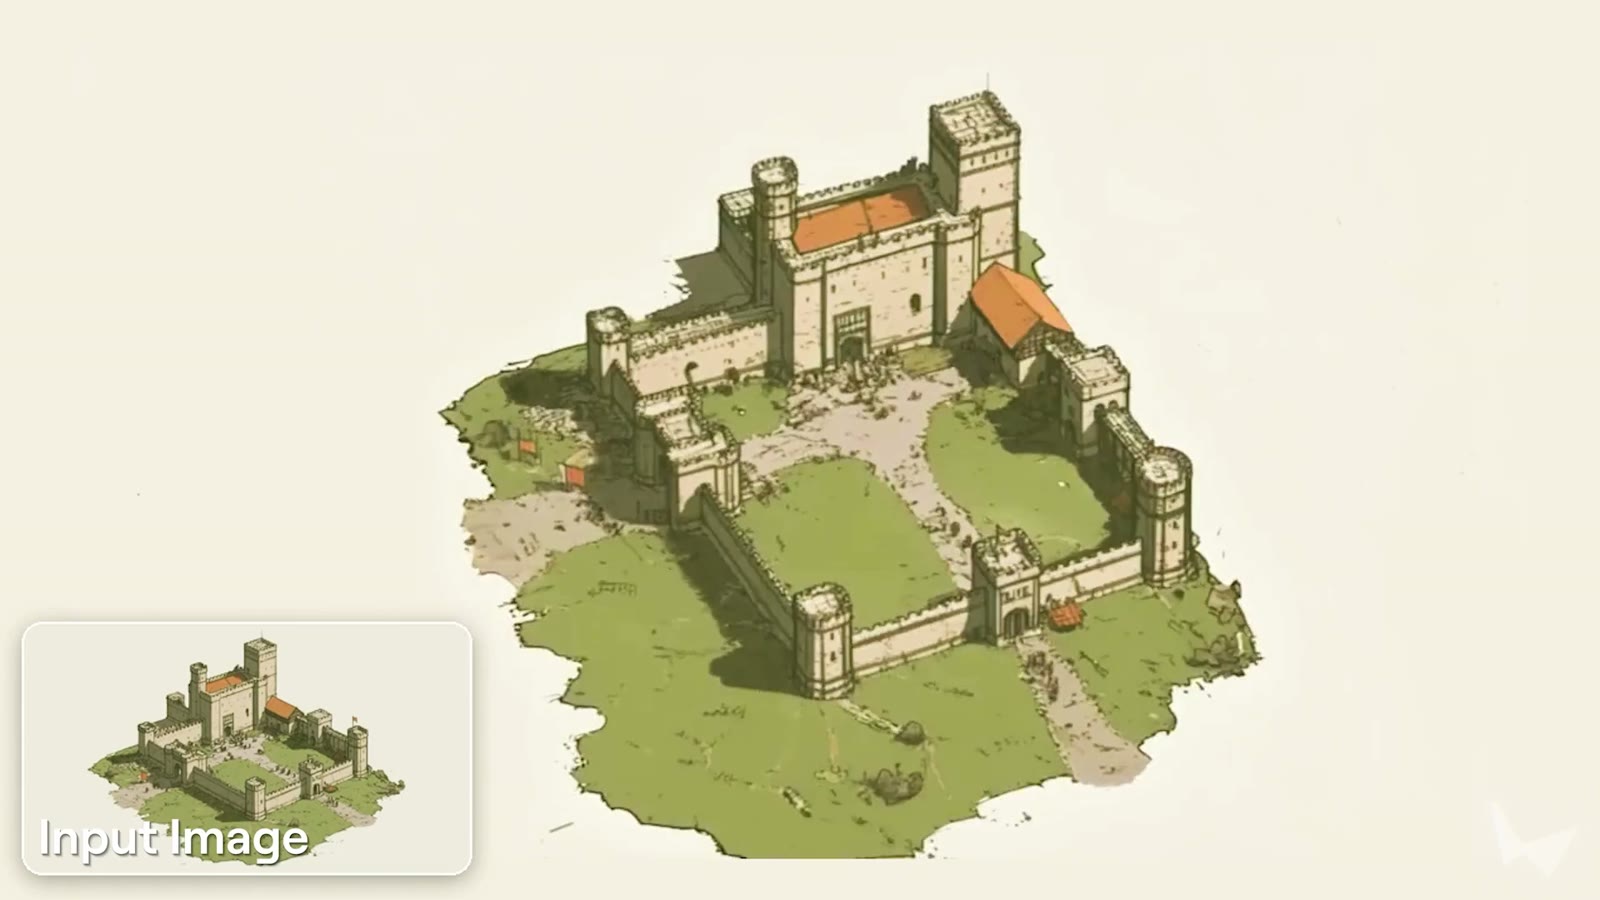
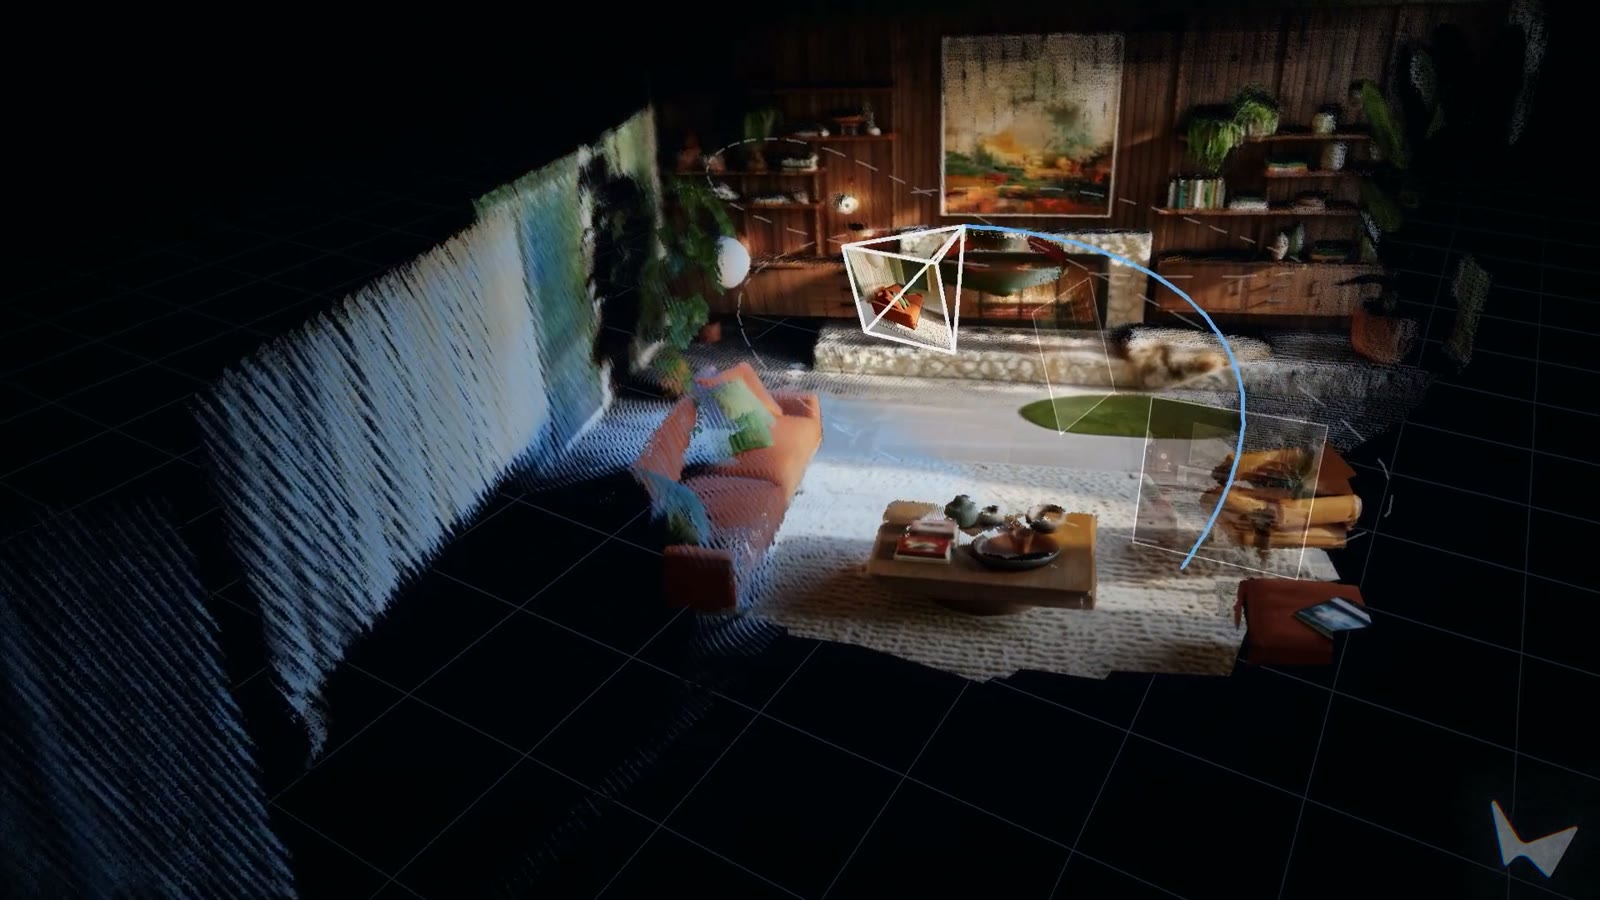
A transparent, coloured blob in space, millions of times over. The technique is from a 2023 SIGGRAPH paper by Kerbl, Kopanas, Leimkühler and Drettakis, 3D Gaussian Splatting for Real-Time Radiance Field Rendering, which proposed to "represent the scene with 3D Gaussians that preserve desirable properties of continuous volumetric radiance fields" and reported "real-time (>= 30 fps) novel-view synthesis at 1080p resolution". Each Gaussian has a position, a shape, an opacity and a view-dependent colour. Stack a few million of them and you have a photoreal scene you can move a camera through.
Alexander Wissner-Gross gave the plainest description I have heard, on the same Moonshots episode: a splat is "basically a transparent blob, an ellipsoid" and "you layer and stack lots of these 3D Gaussian splats on top of each other to create hyperrealistic, traversable 3D scenes". The reason they matter for a web page is speed. Splats are rasterised, not ray-marched, so moving the camera is cheap. That is the same reason a scroll-scrubbed hero feels expensive and costs little, which I covered in the scroll-scrub stack.
What a splat is not: a surface. There is no mesh, no collision, no notion of which blobs are a chair. It is a picture you can walk through, not a model of matter. That was still the state of things in June 2026, when a paper on physics for splat scenes opened by noting that "Production-grade physics engines do not understand the 3DGS representation" (arXiv, 19 June 2026). That gap is why Marble, World Labs' shipping product, exports a collider mesh and a high-quality textured mesh alongside the splats: the splats are for looking, the meshes are for touching.
What did World Labs actually announce?
An omni world model: one network pretrained from scratch on text, images, video and 3D, which generates, reconstructs and simulates spaces instead of only producing clips. The headline capability is camera control, and the announcement post is exact about the number:
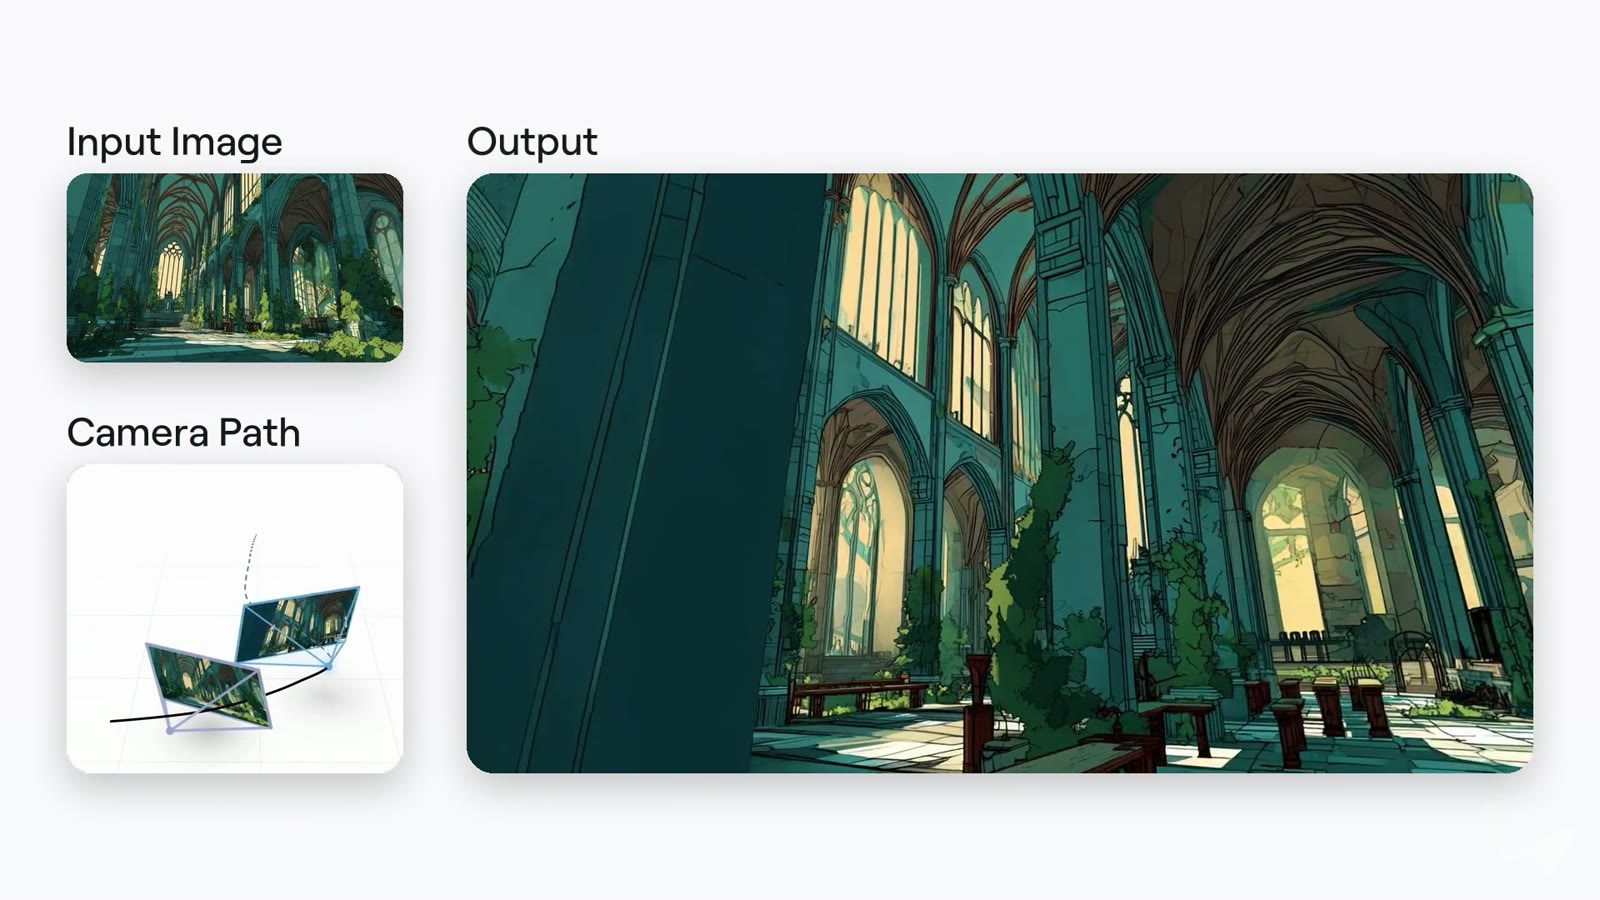
Atlas generates images and videos from one or more images with pixel-perfect camera control, outputting up to 1 minute of video at 1440p.
Camera geometry goes in as a native input type rather than as adjectives in a prompt. The same post frames what that changes: "you are staging the scene, not pulling the lever of a slot machine." Atlas also emits point clouds, depth maps, 3D Gaussian splats and 360 panoramas, and takes one to over a hundred input images. The architecture disclosure is four words long: multimodal autoregressive diffusion transformer. No parameter count, no training compute, no paper, no model card (World Labs, 1 September 2026).
World Labs published two evaluations. On 3D reconstruction from sparse views, Atlas reports a mean absolute-relative pointmap error of 25.3 (times ten to the minus three) averaged across seven benchmarks, against 28.7 for Pi3X and 36.4 for VGGT-Omega 1B. On camera-controlled generation, third-party raters preferred Atlas over MiniMax H3 in 75% of votes and over Gemini Omni Flash in 81%.
Read that second number next to how it was produced. Atlas received the camera path in its native camera format; every baseline received the same path described in words, because none of them accept cameras as input. World Labs says so plainly. So the study measures camera-following, not image quality, motion, audio, speed or cost, and it is self-run and unreplicated. Atlas does not appear on the Artificial Analysis video arena as of 5 September, because nobody outside the partner list can generate with it.
Why are people calling splats a new kind of token?
Because of what the training set is. Wissner-Gross's technical read on Moonshots (from 1:18:36) was that Atlas takes the diffusion transformer "what all state-of-the-art American video generative models use" and adds "one new modality: training it off of text, images, video, AND three- or four-dimensional Gaussian splats". His hedged claim: "for the first time at least at scale, to my knowledge", a lab is "treating 3D Gaussian splats as a first-class training modality alongside pixels from images and tokens from text". And the consequence he draws: if the approach scales, splats "end up becoming a critical new form of token almost for modeling the physical world".
His next step is a conjecture and he labelled it as one, and so do I: "if you can make a world model out of Gaussian splats, you can also make a subatomic model, or an astrophysics-scale relativistic-speeds model, or an inside-the-cell interactions model, just as easily, as soon as you have the data." There is no evidence for that yet. There is a real argument underneath it, though. Language tokens are a lossy transcript of the world. A splat is a measurement of it. If the substrate a model learns from is closer to the thing itself, the hope is that what it learns is closer too.
That is also Yann LeCun's argument, from the other direction. He left Meta to found AMI Labs on the bet that language models are the wrong path, and told MIT Technology Review in January: "They can't truly reason or plan, because they lack a model of the world. They can't predict the consequences of their actions" (MIT Technology Review, 22 January 2026). His alternative learns "the underlying rules of the world from observation, like a baby learning about gravity." Two of the most decorated people in the field are now running companies on the premise that the next frontier is space, not text. They disagree about how, and the disagreement is the interesting part. I come back to it below.
One framing from the same podcast circuit is worth passing on with its label attached. On Moonshots episode 284, the hosts offered the line "America is LLM-pilled and China is world-model-pilled": the language models predict the next token, the world models predict "the next state of reality". It is a slogan, not a study, and Atlas is American, but as a description of where the video and world-model releases of this summer came from it is not far off. The open weights that matter in video this year are Chinese, and the ones that would matter most, Wan 3.0 and MiniMax H3, are either closed or licensed to exclude the United States, which I went through in the video-model shortlist.
Does a model that predicts pixels understand physics?
Not yet, and there is a measurement. Google DeepMind's Physics-IQ benchmark films 66 real physical scenarios from three angles, two takes each, 396 videos in all, spanning solid mechanics, fluid dynamics, optics, thermodynamics and magnetism according to the paper, shows a model the start, and scores what it predicts against what happened. A score of 100 means output that is physically realistic and differs from the truth only in physical randomness. The paper that introduced it is titled as a question, Do generative video models understand physical principles?, and the revised Verified leaderboard on 6 September 2026 answers it in numbers: the best entry, a video-to-video system with a physics reward on top, scores 58.2. Among image-to-video models, NVIDIA's Cosmos3-Super leads at 42.7, MiniMax H3 scores 39.8, Wan 2.2 scores 32.2, Sora 2 scores 26.5.
Hold that next to the preference arenas, where H3 sits near the top on how convincing its clips look. The most persuasive video model of the summer gets four in ten on physics. Visual realism and physical understanding are different quantities, and the industry has been optimising the one that is easy to see. Li supplied the vocabulary for that gap three months before Atlas, in a 3 June 2026 essay that sorts world models into renderers, simulators and planners: "A renderer outputs observations in the form of pixels meant for human eyes, and the quality that matters most is visual fidelity." A simulator, by contrast, "outputs state: a geometrically, physically or dynamically faithful representation of the world that humans and computer programs can both compute on and interact with." Physics-IQ grades renderers on a simulator's job, and the scores say so. Atlas is not on Physics-IQ either, and the coverage of its launch puts the limit plainly: "The more images it receives, the less it has to fill in from its own knowledge" (The Decoder, 2 September 2026). Filled in is the operative phrase for the whole category.
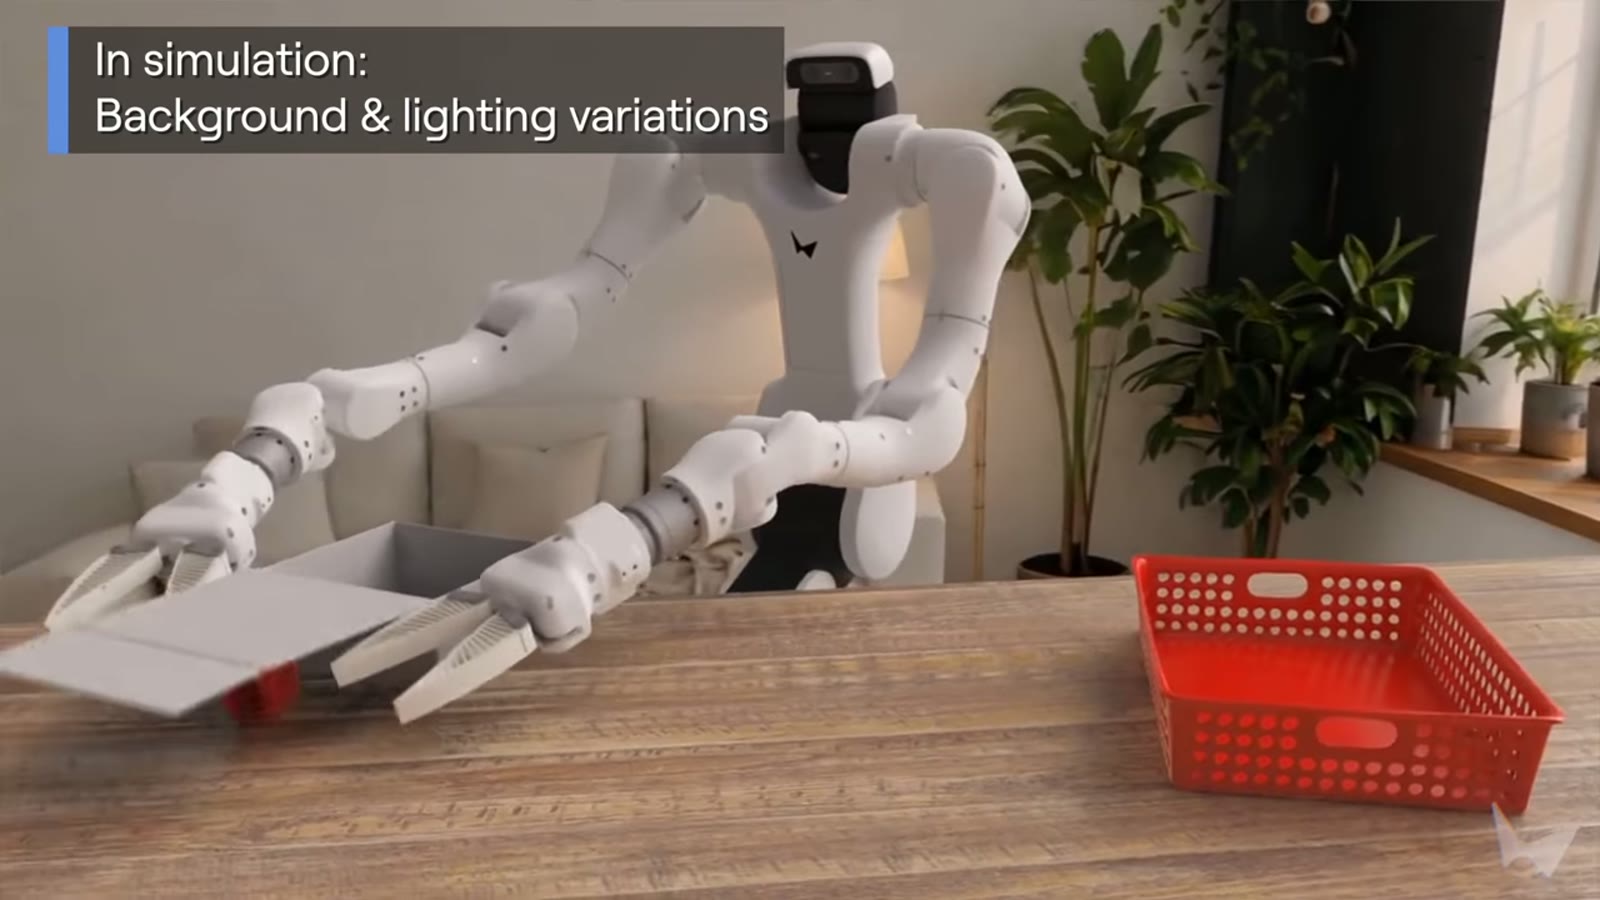
So what are world models for, if not physics? Training robots, mostly, and the people building robots say so. On All-In's robot episode in late July, Bernt Børnich, founder and CEO of 1X, said the company started a world-model lab because "we now finally have the scaling laws on that", and that its Neo robot would let outside world models be plugged in (All-In, 29 July 2026, from 25:23 and 21:13). Emad Mostaque on Moonshots: robots "are not going to be trained in the real world, they're going to be trained in these high-fidelity simulation worlds." Wissner-Gross's reply: "That's the present." A model that gets physics four times in ten is a poor physicist and a useful place to fall over a million times before the real hardware does. That is a smaller claim than "AI understands the world", and it is the one the evidence supports.
Prediction or understanding: the disagreement worth watching
Here is the philosophical split, stated as plainly as I can. World Labs and every video lab generate the pixels: the model's belief about the world is expressed by drawing it. LeCun's position is that this is doomed in principle: "The world is unpredictable. If you try to build a generative model that predicts every detail of the future, it will fail." His architecture predicts in an abstract space and refuses to draw the leaves on the trees. Fei-Fei Li's essay asks for "perceptual, geometrical, and physical consistency" in the drawing itself.
I do not know who is right, and I notice that the people who do claim to know are mostly selling one side. What I can say is that both camps have quietly agreed on the premise, which is that intelligence needs a model of space and consequence, and that words alone will not produce one. That is a real change from two years ago, when the argument was about how many more tokens it would take. Physics-IQ is the referee neither camp controls. The number to watch over the next year is not an arena Elo, it is whether anything crosses 60 on the Verified board without a physics reward bolted on afterwards.
What can a studio my size do with it today?
Buy Marble, not Atlas. Marble has been generally available since November 2025 and its World API pricing page publishes the credit cost of every event and then the observed distribution of real charges. A standard world from a photograph is 1,580 credits at 1,250 credits to the dollar, about $1.26. The high-quality textured mesh is the expensive export at $2.80, takes up to an hour, and is limited to four per hour. PLY splat export is free. In the Marble app, exporting at all needs the Standard plan and commercial rights need Pro; the API is priced separately and its outputs are commercial by default.
The world reaches a web page through Spark, World Labs' open-source splat renderer for three.js, MIT licensed, 2.1.0 against three.js 0.180 on WebGL2, reading PLY, SPZ, SPLAT, KSPLAT and SOG. The getting-started block is short:
import { SparkRenderer, SplatMesh } from "@sparkjsdev/spark";
const spark = new SparkRenderer({ renderer });
scene.add(spark);
const world = new SplatMesh({ url: splatURL });
world.quaternion.set(1, 0, 0, 0);
scene.add(world);
That quaternion is a 180 degree turn about X, there because of a line in the export FAQ:
Default world labs worlds are in OpenCV coordinate system (+x left, +y down, +z forward). Many DCC software are in the OpenGL coordinate system (+x left, -y down, -z forward). To correct for it, perform an OpenCV-to-OpenGL transformation by scaling the Y and Z axes by -1.
Skip it and the world loads upside down with no error, the most expensive kind of wrong. I lost an afternoon to a cousin of this bug in a Blender export, told in procedural geometry versus Blender. Splats are now the third answer to the question that post asks, alongside code and modelling.
The phone is the constraint, and World Labs says so in the Spark 2.0 write-up: "most consumer devices can only render 1-5M splats at interactive frame rates. Large scenes need to download 100+ MB or even 1+ GB 3DGS data before displaying it." Marble therefore exports two tiers, about 2M splats and about 500k, and Spark 2.0 added a streaming format chunked at 64K splats so a scene appears coarse and refines. Nobody has published load times for the 500k tier on a real phone over cellular. That is the first experiment I would run, and the only three that matter for a marketing site are:
- One room as a section inside an existing scroll page, camera on the scroll position, page still working if the file never arrives.
- A walkthrough from a dozen photographs a client already has, at about $1.28 a render on the standard model and up to $2.48 on Plus, against the price of a scanning service.
- The 500k versus 2M test: SPZ bytes and time-to-first-frame on an actual iPhone, before any of this reaches a proposal.
And the terms, briefly: under the terms updated 21 January 2026, paid and API users own their outputs and may use them commercially; free accounts get a revocable, non-commercial licence; World Labs takes a licence to use your uploads for product development and model training, irrevocable for free accounts and revocable prospectively for paid ones; and on World Labs' reasonable request, distributed outputs carry an attribution line. Client photographs are client property, so the opt-out belongs to them, and it goes in the engagement letter before the first upload. Check the MLS's rules on altered or generated images before anything like this touches a listing.
I filled in the Atlas request form on the day it opened. Until somebody outside the partner list can call it, the defensible things to say about Atlas are the three in its own post: one minute, 1440p, a camera you draw. The number I most want is not in the post at all, and if Fei-Fei Li does appear on Moonshots in a couple of weeks, the first thing I will listen for is a frame rate.
Common questions
What is World Labs Atlas?
An omni world model announced on 1 September 2026: one network trained on text, images, video and 3D that generates camera-controlled video up to one minute at 1440p, plus point clouds, depth maps, Gaussian splats and panoramas. It is early access only, with no public API, price or paper.
Who is Fei-Fei Li?
The co-founder of World Labs, who leads the company, a Stanford computer science professor and co-director of Stanford HAI, and the researcher who led ImageNet. Her November 2025 essay From Words to Worlds sets out the case for spatial intelligence as the frontier beyond language.
What is a Gaussian splat?
A 3D scene representation from a 2023 SIGGRAPH paper: millions of transparent, coloured ellipsoids with position, shape, opacity and view-dependent colour, rasterised in real time. It renders fast but has no surfaces, collision or semantics on its own.
Do video and world models understand physics?
Not by the available measurement. On Google DeepMind's Physics-IQ benchmark as of 6 September 2026, NVIDIA Cosmos3-Super leads image-to-video at 42.7, MiniMax H3 scores 39.8, Wan 2.2 scores 32.2 and Sora 2 scores 26.5 out of 100; the best entry overall, with a physics reward added, scores 58.2.
What can a small studio use today?
Marble, World Labs' shipping product, at about $1.26 per generated world through the API, with free PLY splat export, and Spark, the MIT-licensed three.js renderer that loads the result in a web page. Export the 500k-splat tier for phones and test it on a real device over cellular.
Related